The Total Cost of AI (TCA) answers a question most organizations cannot yet answer: what does it cost to deliver an AI-enhanced product, and is that cost justified by the outcome? Most organizations can report what they spent with a model provider. Few can say what one product’s AI capability costs once shared platforms, platform teams, idle commitments, and engineering labor are counted, which makes AI return on investment (ROI) claims hard to defend. In the September 2026 State of Tokenomics survey of 472 organizations, 43 percent named proving value or ROI as their top challenge, and nearly three in four could not confidently connect AI spend to an outcome their CFO would accept.
Two terms appear throughout this piece. AI FinOps is the practice of managing AI spend: what AI costs to supply and whether that spend is efficient. AI Economics (also called Tokenomics) is the microeconomic impact of AI on the whole company: what AI changes about how the company makes money and does work, with value measured in CFO terms such as revenue and margin. AI Economics is not a team or a role. It is a responsibility shared across the C-suite, and it depends on the cost foundation AI FinOps provides.
TCA is a two-step model joined by an allocation step:
This explainer covers both steps: the data AI FinOps must gather and the rate it produces, how that rate is combined with Product TCA, and how product owners and finance turn it into a product-level economic fact that can be paired with value to calculate ROI.
TCA must be measured where value is created, and AI creates value through products. A model invoice says nothing about return until it is tied to the product whose AI enhancement earns revenue, saves time, or reduces risk.
For the same reason, a showback of model and token spend leaves out costs. Products also consume the organization’s own shared AI capacity, such as gateways, GPU clusters, and the people who run them. Each product should carry its fair share of those costs, using the same consumption-based logic AI FinOps already applies to the cloud.
AI FinOps pools shared costs into one rate per delivery path; allocation prices each product’s usage at that rate; product teams add product-specific costs to reach the TCA where value is claimed.

The core AI FinOps deliverable is a rate card per delivery path that reflects every cost of providing AI capacity. A delivery path is how capacity is bought: self-hosted or on-premises, a cloud service provider (CSP) hosted service, a model provider API, a seat-based subscription, or AI embedded in SaaS.
This is familiar work applied to a new category. The FinOps Framework building blocks map directly:
Five fundamental data sets capture what organizations pay providers, people, and shared infrastructure to make AI run.
| Data set | What it contains | Why it matters |
|---|---|---|
| Billing and consumption | Invoices and usage from model providers, cloud, and AI SaaS, ideally normalized to the FinOps Open Cost and Usage Specification (FOCUS) | The direct baseline |
| Allocation metadata | Tags, API keys, gateway logs, and model identifiers tying spend to a team, product, or use case | Unlocks value classification |
| Rate and commitment | Contracts, negotiated discounts, reserved capacity, and amortization schedules | Measures effective cost |
| Labor and operating cost | Time and fully loaded costs for engineering, data science, MLOps, evaluation, and support, from HR, portfolio management, or time tracking systems | The largest and least visible component |
| Supporting and shared infrastructure | Data acquisition and preparation, storage, networking, security, governance and compliance tooling, observability, power, space, and hardware depreciation | Essential for self-hosted and on-premises workloads |
AI FinOps proposes five cost pools of usage data sets. Together they form the numerator of the rate; units delivered (tokens or active seats) form the denominator.
| Cost pool | What it includes | How it enters the rate |
|---|---|---|
| Direct consumption or capacity | Metered model spend, prepaid commitments and credits, CSP provisioned throughput, seat licenses, amortized accelerators and facilities | Assigned to the delivery path it was bought for; split by budgeted consumption |
| Shared infrastructure | Gateways, routers, data pipelines, observability, logging, platform-level auditing, hardware, data center fixed costs | Spread across the delivery paths that use it |
| Platform labor | AI center of excellence (COE), GPU or token factory team, enablement, governance | COE and governance spread across all paths; GPU team labor to the on-premises path |
| Platform-provision costs | Fine-tuning offered as a shared capability, model licensing, org-wide data stores | Spread across the delivery paths using those platforms |
| Idle and committed waste | Unused prepaid commitments, idle provisioned throughput, idle accelerators, inactive seats | Assigned to the delivery path it was bought for; split by budgeted resources |
Two pools deserve attention. Platform labor spans both steps: the COE and GPU teams sit in the rate, while product delivery labor sits in Step 2, and clear boundaries prevent double counting. Idle and committed waste must be visible in the rate: if unused capacity is allocated to products later, a product’s rate can jump with no change in its own behavior, which undermines trust in the ROI figures built on it.
The result is a simple ratio for each delivery path:
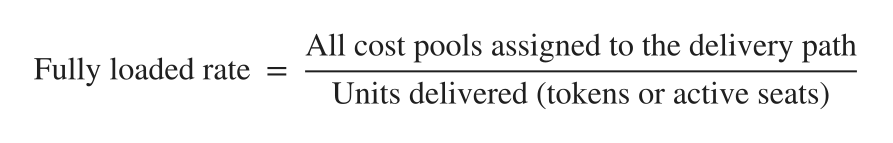
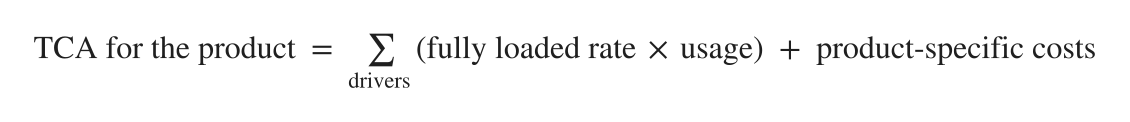
Allocation is the bridge between the two steps: each product is charged the fully loaded rate of the delivery path it uses, multiplied by its usage.
This keeps responsibilities clean. AI FinOps answers “What does one unit of AI cost us, all in?” once per period. Product teams answer “How many units did this product use, and for what?” Because the rate already carries shared and idle costs, products pay their fair share without each team rebuilding the platform’s economics.
The split reflects who holds the data and who makes the decisions. Platform and AI FinOps teams see invoices, commitments, and shared infrastructure. Product teams see why AI is consumed, what it enables, and what outcome it produces. Asking platform and FinOps teams to do the product teams’ job, or the reverse, yields a rate with no business context or a business case with no defensible cost.
AI FinOps continues to support Step 2 by:
Product TCA turns shared rates into the TCA of one product, and that is where value is claimed. It converts AI from a shared platform expense into a product-level economic fact. Without Step 2, organizations know what AI costs in aggregate but not what it costs to produce a result. This result feeds AI Economics, the shared C-suite conversation.
A driver is a distinct reason a product consumes AI. There are three:
Separating drivers matters because each behaves differently. Runtime cost scales with customer demand and is the core of unit economics. Build and maintain cost tracks the product’s rate of change. Team assistant cost tracks headcount and working practices. A single blended number hides which lever to pull.
The second component covers costs that exist because this product has AI capabilities:
Labor is the largest and least visible part of TCA. Token spend is metered to the decimal, while the engineers, data scientists, and reviewers who make the product work are often missing from AI cost reporting entirely. In the State of FinOps 2026 survey of 1,192 practitioners, 28 percent reported managing or planning to manage labor costs. Product TCA brings them into the picture.
Product TCA is an input to the decisions AI Economics covers. AI’s microeconomic impact on a company shows up in three places:
Product TCA is the input to decisions about pricing, staffing, and which products deserve further investment.
Value is claimed and measured at Step 2, through cost per outcome and return on AI. Value comes from the product’s AI enhancement, such as faster claims processing, higher conversion, or fewer support escalations. Product TCA matches the cost to that outcome.
This is the bridge to AI value classification. Once TCA is assembled per product, it can be paired with the product’s classified value (revenue growth, cost avoidance, risk reduction, or productivity) to calculate an ROI that holds up to scrutiny from finance.
Start small. One product with good metadata and an engaged owner will teach more than an enterprise-wide model built on estimates.
| Term | Definition |
|---|---|
| Capacity share | The share of a person’s working time assigned to a product, taken from human capacity management data. |
| Delivery path | How AI capacity is provided and bought: self-hosted, CSP-hosted service, model provider API, seat-based subscription, or SaaS-embedded AI. Each has a rate card of available models and rates. |
| Driver | A distinct reason a product consumes AI: product runtime, build and maintain, or team agents and assistants. |
| Fully loaded rate | The cost of one unit of AI delivered (a million tokens, an active seat-month) with every Step 1 cost included, produced separately for each delivery path. |
| Product | A technology product or service that provides a business outcome. |
| Total Cost of AI (TCA) | The full Step 2 cost of a product: AI consumption across the three drivers plus the product-specific costs that enable its AI capabilities. |
AI ROI can only be as credible as the cost beneath it. AI FinOps makes that cost complete; AI Economics looks at decisions made about pricing, staffing, and investment. The next step is to join product-level TCA with AI Value Classification to produce a repeatable method for measuring return on AI.
We invite AI FinOps practitioners, product owners, and finance leaders to:
Start with one rate card and one product this quarter.
The FinOps Foundation would like to thank the following people for their work:






Last updated: November 18, 2026